Transformer encoder–decoder in 3D
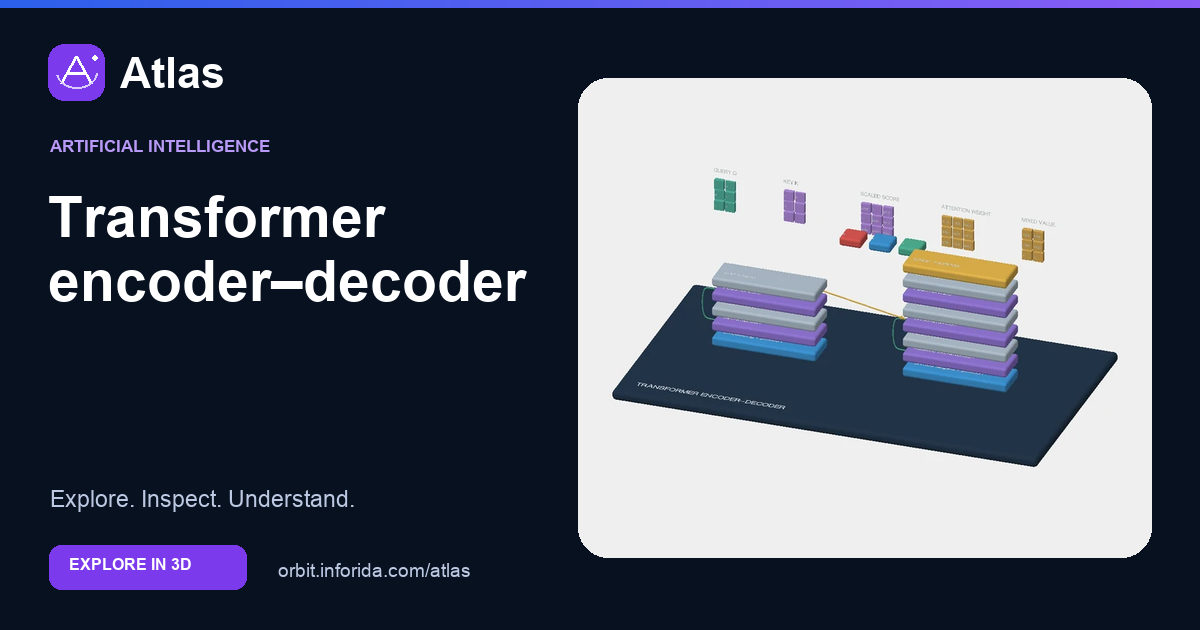
Separate encoder attention, masked decoding and cross-attention. Explore the 3D model, inspect its parts and learn with guided explanations. Free on Atlas.
What you can learn
Separate encoder attention, masked decoding and cross-attention.
Give tokens a representation and position.
Build contextual input representations.
Keep future target tokens masked.
Try an investigation
Trace input representation toward scaled dot-product attention. Which intermediate operations or assemblies are essential, and which assumptions are simplified by this diagram?
Check your understanding
The decoder cross-attention consults…
Encoder representations. Encoder representations. The exhibit shows computational roles and dependencies; it does not contain trained parameters or run inference.
Positional information provides…
A representation of order. A representation of order. The exhibit shows computational roles and dependencies; it does not contain trained parameters or run inference.
Queries and keys determine…
Attention comparison scores. Attention comparison scores. The exhibit shows computational roles and dependencies; it does not contain trained parameters or run inference.
Sources and model scope
A three-dimensional computational diagram, not physical hardware or a running trained model. Displayed widths, node counts and example values are illustrative. Select named stages to trace information flow. The separate upper study rail contains deterministic worked examples, with values on every selectable cell.